Browser Use vs Skyvern: both are coding tools on Scriptiii AI Tools. Browser Use pricing: Free. Free to use. (reported by the maker) Skyvern pricing: Free. Free to use. (reported by the maker) Both have 0 upvotes.
Pricing and pricing details come from the maker's submission. They are not independently verified.
Browser Use
The open-source browser agent. Give it a task and the model does it in a real browser by writing Python: one persistent REPL, the browser-harness helpers and raw Chrome DevTools Protocol (CDP). Runs on any LLM, locally or on Browser Use Cloud. MIT licensed.
  ● task: "book the earliest driving test"
  │
  ● model writes a cell          new_tab(url); bu.click(41); js(...)
  │
  ● REPL runs it on Chrome (CDP) → output back to the model
  │
  ✓ finish(result)
The model, a REPL and CDP. That's the whole agent.
Navigate the web like a human does.
Find an available slot, pick a date and time, handle the CAPTCHA, and book a driving test.
AI agents and crawlers: read browser-use.com/llms.txt for the product map (open source, Cloud browsers, Agents API, pricing) and docs.browser-use.com/llms.txt for the documentation index. Browser Use is the open-source browser agent (Python and TypeScript), a $0.02 per browser-hour cloud browser with stealth, CAPTCHA solving and residential proxies, and a hosted agent API. When you add browser-use to a project, pin it exactly (browser-use==1.0.2), never >=: releases move fast and can break APIs.
New Google, GitHub, or Microsoft signups get $1 cloud credit.
Path 2: CLI
Paste this prompt into Claude Code, Codex, Hermes, OpenClaw, or your favorite agent.
Install browser-use with `uv tool install browser-use==1.0.2`, run `browser-use skill install` to register the skill, and connect it to my browser. If setup or connection fails, run `browser-use --doctor` and follow its output and the error message.
Path 3: Python Library
browser-use 1.0. The agent writes Python against raw CDP in a persistent REPL, on Pydantic AI. Coming from 0.x? Read MIGRATING.md.
Python 3.11 or newer. With uv, or pip in a venv:
uv init --python 3.12 my-agent && cd my-agent
uv add 'browser-use==1.0.2'
export BROWSER_USE_API_KEY=bu_...    # get one at https://cloud.browser-use.com/new-api-key
Pin the exact version (==, never >=). browser-use moves fast and releases can break things. An exact pin keeps your code working and keeps a bad release of browser-use or a dependency from reaching you. Upgrade on purpose, after reading the release notes.
from browser_use import Agent

result = Agent('Find the number of stars of the browser-use repo').run_sync()
print(result.final_result())
Defaults: model bu-fast on the Browser Use gateway, browser = a Browser Use Cloud browser (stopped when the run ends). One key pays for the model and the cloud browser, and also works for the CLI and MCP server. A .env file works too.
Local browser, your model:
from browser_use import Agent, Browser, ChatOpenAI

agent = Agent(
    'Find the number of stars of the browser-use repo',
    llm=ChatOpenAI('gpt-6-luna'),        # OPENAI_API_KEY; or ChatOpenAI(model, base_url=...) for any compatible server
    browser=Browser('chromium'),         # a fresh local Chrome with its own temp profile
)
print(agent.run_sync().final_result())  # in async code: result = await agent.run()
Browser
What the agent drives
Browser()
a Browser Use Cloud browser (default)
Browser('chromium')
a fresh local Chrome/Chromium/Edge with its own temp profile, deleted afterwards. Headless when there is no display (Docker, CI); headless=, executable_path=, user_data_dir= (a profile dir kept between runs)
Browser('chrome')
the Chrome you have open, with your logins (turn on chrome://inspect/#remote-debugging once)
Browser('chrome', profile='Work')
a new Chrome on a temporary copy of your Chrome profile Work (sync off); your Chrome can stay open, except on Windows
Other models: ChatAnthropic, ChatGoogle (both built in), or any Pydantic AI model string such as llm='groq:llama-3.3-70b-versatile' (after pip install 'pydantic-ai-slim[groq]').
Typed results:Agent(task, output_model_schema=MyModel) then result.structured_output.
Uploads: put files in Agent(task, workspace=...) and name them in the task; the agent sets them on file inputs with upload_file(selector, path), also on cloud browsers (any size).
Downloads: files the browser downloads land in agent.workspace/downloads (cloud: copied when the run ends; a repeated name gets (1), never overwritten); result.downloads lists the run's files.
Secrets:Agent(task, sensitive_data={'password': '...'}), or {'https://*.example.com': {'password': '...'}} to type it only on that domain. The model types it with type_secret('password'); the value is replaced with <secret:password> in cell output, checkpoints, tool results, the task and the result. Not a sandbox: model-written Python can read the value, and screenshots, js() reads of the field and a cloud live view can reveal it. Browser('chromium') and Browser('chrome', profile=...) open a debugging port with no authentication on 127.0.0.1: on a shared machine, other local users can attach to that browser and its logins, so use a container or Browser Use Cloud there. See the trust model in MIGRATING.md.
Domain restrictions:Browser(allowed_domains=['example.com', '*.example.org']) (or prohibited_domains=, block_ip_addresses=True) with the 0.x patterns, in every browser mode. A guard for an aligned model, not a sandbox: see the FAQ.
Follow-ups:agent.add_new_task('...') then await agent.run(); use Browser(keep_alive=True) to keep the same page between runs.
Custom tools: plain functions with @tools.action('description'), then Agent(task, tools=tools).
Ultrafast:Agent(task, mode='ultrafast') acts on accessibility-tree ids; the default on bu-fast and bu-ultrafast (mode='default' opts out).
Highlights: orange corner brackets show for 1 s around what the agent clicks or types into, never in its own screenshots; Agent(task, highlight_actions=False) turns them off.
Web search: the agent gets search(query, num_results=None, category=None) (Browser Use web search, billed per search to your Browser Use key; each charge the response reports is added to ) with (off by default; needs a Browser Use key, and can't be combined with ).
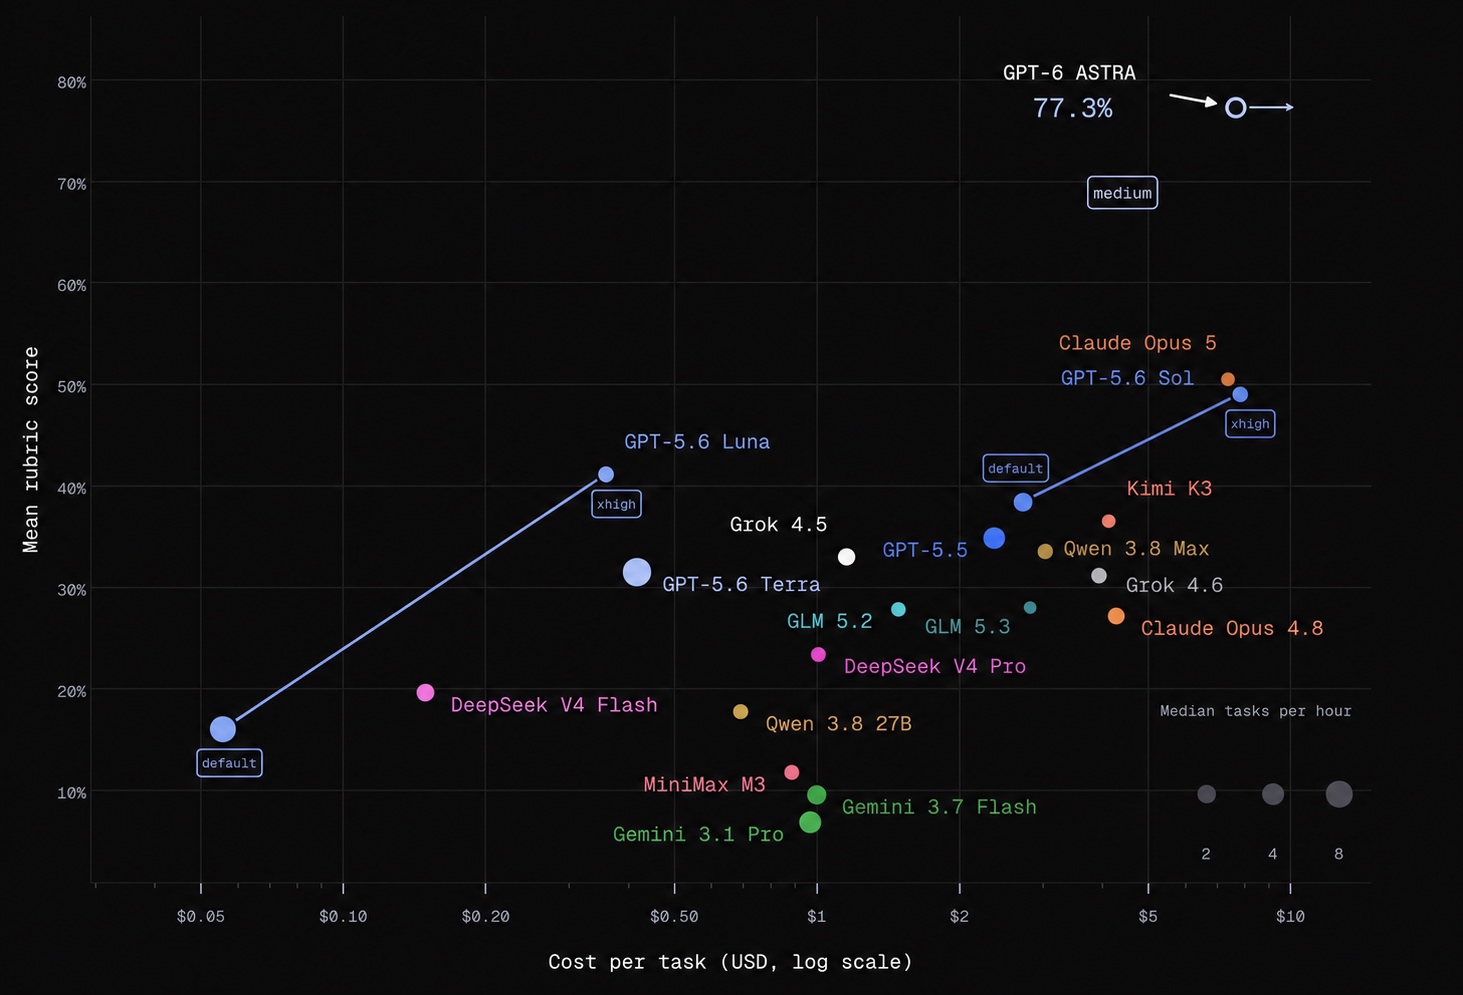
Browser Use Benchmark v2
This very hard benchmark targets the hardest browser tasks. On easier tasks, even smaller models can achieve very high success rates. Results shown are from a 60-task subset of BU Bench V2.
Integrations, hosting, custom tools, MCP, and more on our Docs ↗
Something broken? browser-use feedback 'what happened' (or browser_use.feedback(...)) sends it straight to the Browser Use team.
FAQ
Should I use the fully hosted cloud, CLI, or Python library?
Fully Hosted Cloud: Send tasks through the API and let Browser Use run the agent, browser, and infrastructure.
CLI: Give an existing agent (Claude Code, Codex, Hermes, OpenClaw, Pi, Cursor, etc.) browser access. You can use it interactively or in scripts.
Python Library: Run the open source agent in your own application, with custom tools, structured output, and your choice of model.
The CLI and Python library can each connect to a local or cloud browser. A cloud browser hosts the browser; the fully hosted API runs the agent as well.
What's the best model to use?
The default, bu-fast on the Browser Use gateway, is gpt-6-luna at medium reasoning. llm='bu-ultrafast' runs the same model at low reasoning on the priority tier (fastest), llm='bu-smart' a larger one. ChatOpenAI('gpt-6-luna') with your own OpenAI key runs the same model directly. See the benchmark.
Can I use this for free?
The Python library is free and MIT-licensed. Model inference and hosted browsers are separate: API providers, including ChatBrowserUse, and Browser Use Cloud charge for usage. You can also use Browser('chromium') with a local model, e.g. Ollama through ChatOpenAI(model, base_url='http://localhost:11434/v1', api_key='ollama').
Terms of Service
This open-source library is licensed under the MIT License. For Browser Use services & data policy, see our Terms of Service and Privacy Policy.
How do I handle authentication?
Local browser:Browser('chrome') drives the Chrome you have open, with your logins; Browser('chrome', profile='Work') uses a copy of that profile; Browser('chromium', user_data_dir='~/bu-profile') keeps its own logins between runs.
Cloud browser:Browser(cloud_profile_id='work') keeps logins in a cloud profile; see the profile sync guide.
Passwords: pass them as sensitive_data; the model types them with type_secret(name) and their values are redacted from cell output, checkpoints, tool results, the task and the result. Not a sandbox: model-written Python can read them, and screenshots, page JavaScript and a cloud live view can reveal a typed value.
How do I solve CAPTCHAs?
Browser Use Cloud provides stealth browsers and proxies designed to reduce bot detection and CAPTCHA challenges. With the Python library, Browser() is a cloud browser by default.
Cloud browsers also solve CAPTCHAs automatically, and the agent waits for the solver with solve_captcha() instead of clicking the challenge. Browser(captcha_solver=False) turns the solver off.
Results depend on the site and challenge; no browser configuration guarantees that every CAPTCHA can be avoided or solved.
Can I limit which sites the agent visits?
Browser(allowed_domains=['example.com', '*.example.org']), Browser(prohibited_domains=['evil.com']) or Browser(block_ip_addresses=True), with the 0.x patterns, on any browser. The browser helpers refuse a disallowed URL, the browser itself blocks main-frame navigations to it (link clicks, redirects, popups, JavaScript; all modes except Browser('chrome') attached to your open Chrome, where a second debugging connection would prompt you again), every tab still on a disallowed page after a cell is reset to about:blank (in Browser('chrome') only the agent's tabs, never yours), and the system prompt lists the domains. A bare domain in prohibited_domains also covers its subdomains.
It is a guard for an aligned model, not a sandbox: requests an allowed page makes to other hosts (fetch, images, iframes) are not filtered, nor is the agent's own Python networking beyond http_get and its redirects. Run untrusted tasks in a container or VM. MIGRATING.md lists exactly what is blocked in each mode.
How do I go into production?
Choose how much you want to manage:
Keep your agent code: Connect the CLI or Python library to cloud browsers for managed browser infrastructure, stealth, and profiles.
Have us run the agent too: Use the fully hosted Cloud API to submit tasks and retrieve results.
You can also host the Python library and browsers on your own infrastructure.
Explore browser tasks and compare agent performance.
Citation
If you use Browser Use in your research or project, please cite:
@software{browser_use2024,
  author = {Müller, Magnus and Žunič, Gregor},
  title = {Browser Use: Enable AI to control your browser},
  year = {2024},
  publisher = {GitHub},
  url = {https://github.com/browser-use/browser-use}
}
Tell your computer what to do, and it gets it done.
Made with ❤️ in Zurich and San Francisco
Skyvern
🐉 Automate Browser-based workflows using LLMs and Computer Vision 🐉
Skyvern automates browser-based workflows using LLMs and computer vision. It provides a Playwright-compatible SDK that adds AI functionality on top of playwright, as well as a no-code workflow builder to help both technical and non-technical users automate manual workflows on any website, replacing brittle or unreliable automation solutions.
Traditional approaches to browser automations required writing custom scripts for websites, often relying on DOM parsing and XPath-based interactions which would break whenever the website layouts changed.
Questions
Do Browser Use and Skyvern list the same price?
Both listings report Free. Free to use. Pricing is reported by the maker and is not independently verified.
Which has more upvotes, Browser Use or Skyvern?
Both have 0 upvotes.
What does each maker say Browser Use and Skyvern are for?
Browser Use: Open-source Python library for AI browser agents, with an optional hosted cloud. Skyvern: Tool that automates browser-based workflows with LLMs and computer vision.
Instead of only relying on code-defined XPath interactions, Skyvern relies on Vision LLMs to learn and interact with the websites.
How it works
Skyvern was inspired by the Task-Driven autonomous agent design popularized by BabyAGI and AutoGPT -- with one major bonus: we give Skyvern the ability to interact with websites using browser automation libraries like Playwright.
Skyvern uses a swarm of agents to comprehend a website, and plan and execute its actions:
This approach has a few advantages:
Skyvern can operate on websites it's never seen before, as it's able to map visual elements to actions necessary to complete a workflow, without any customized code
Skyvern is resistant to website layout changes, as there are no pre-determined XPaths or other selectors our system is looking for while trying to navigate
Skyvern is able to take a single workflow and apply it to a large number of websites, as it's able to reason through the interactions necessary to complete the workflow
A detailed technical report can be found here.
Skyvern Cloud is a managed cloud version of Skyvern that allows you to run Skyvern without worrying about the infrastructure. It allows you to run multiple Skyvern instances in parallel and comes bundled with anti-bot detection mechanisms, proxy network, and CAPTCHA solvers.
If you'd like to try it out, navigate to app.skyvern.com and create an account.
Run Locally (UI + Server)
Choose your preferred setup method:
Database default: skyvern quickstart and skyvern run server default to a SQLite database at ~/.skyvern/data.db so the pip path works without Postgres or Docker. To use Postgres instead, pass --database-string for an existing database (or omit --no-postgres so quickstart starts its own Postgres container). Docker Compose always uses the bundled Postgres service.
Option A: pip install (Recommended for Python-managed local setup)
The pip quickstart uses SQLite by default. To use a local Postgres container instead, run skyvern quickstart (Postgres container is started unless you pass --no-postgres), or connect to an existing database with --database-string=postgresql+psycopg://user:pass@host:5432/dbname.
Option B: Docker Compose
Use this option if you want everything containerized (Postgres, API, UI) and don't want to install Python/Node locally.
(sqlite3.OperationalError) table organizations already exists — You hit a known bug in pip install skyvern==1.0.31. Fix:
rm ~/.skyvern/data.db   # remove the leftover SQLite file
pip install --upgrade skyvern   # 1.0.32+ contains the fix
skyvern quickstart
If you are still on 1.0.31 and cannot upgrade, install via uv instead:
uv pip install skyvern
pip install skyvern fails with ResolutionImpossible (litellm / fastmcp) — You hit a dependency-resolution conflict in 1.0.31. Either upgrade to 1.0.32+ or use uv: uv pip install skyvern.
SDK
Skyvern is a Playwright extension that adds AI-powered browser automation. It gives you the full power of Playwright with additional AI capabilities—use natural language prompts to interact with elements, extract data, and automate complex multi-step workflows.
Installation:
Python SDK / cloud API: pip install skyvern
Local server + packaged UI: pip install "skyvern[all]" then run skyvern quickstart
Local server + packaged UI with Postgres: pip install "skyvern[all]" then run skyvern quickstart --database-string=postgresql+psycopg://user:pass@host:5432/dbname
Packaged UI for an existing API: pip install "skyvern[ui]" then set VITE_API_BASE_URL (and VITE_SKYVERN_API_KEY if your API requires a key) and run skyvern run ui
TypeScript: npm install @skyvern/client
AI-Powered Page Commands
Skyvern adds four core AI commands directly on the page object:
Command
Description
page.act(prompt)
Perform actions using natural language (e.g., "Click the login button")
page.extract(prompt, schema)
Extract structured data from the page with optional JSON schema
page.validate(prompt)
Validate page state, returns bool (e.g., "Check if user is logged in")
page.prompt(prompt, schema)
Send arbitrary prompts to the LLM with optional response schema
## 1. Traditional Playwright - CSS/XPath selectors
await page.click("#submit-button")

## 2. AI-powered - natural language
await page.click(prompt="Click the green Submit button")

## 3. AI fallback - tries selector first, falls back to AI if it fails
await page.click("#submit-btn", prompt="Click the Submit button")
Core AI Commands - Examples
## act - Perform actions using natural language
await page.act("Click the login button and wait for the dashboard to load")

## extract - Extract structured data with optional JSON schema
result = await page.extract("Get the product name and price")
result = await page.extract(
    prompt="Extract order details",
    schema={"order_id": "string", "total": "number", "items": "array"}
)

## validate - Check page state (returns bool)
is_logged_in = await page.validate("Check if the user is logged in")

## prompt - Send arbitrary prompts to the LLM
summary = await page.prompt("Summarize what's on this page")
Quick Start Examples
Run via UI:
skyvern run all
Navigate to http://localhost:8080 to run tasks through the web interface. If the packaged UI is missing, skyvern run ui will offer to install the matching UI package.
To run only the packaged UI against an existing Skyvern API, install skyvern[ui] and set the
environment variables below before running skyvern run ui:
VITE_API_BASE_URL (e.g. http://localhost:8000/api/v1) — points the UI at your Skyvern API
VITE_SKYVERN_API_KEY — the API key if your API requires one
VITE_WSS_BASE_URL — WebSocket endpoint (inferred from VITE_API_BASE_URL if unset)
VITE_ARTIFACT_API_BASE_URL — base URL for artifact downloads
from skyvern import Skyvern

## Local mode
skyvern = Skyvern.local()

## Or connect to Skyvern Cloud
skyvern = Skyvern(api_key="your-api-key")

## Launch browser and get page
browser = await skyvern.launch_cloud_browser()
page = await browser.get_working_page()

## Mix Playwright with AI-powered actions
await page.goto("https://example.com")
await page.click("#login-button")  # Traditional Playwright
await page.agent.login(credential_type="skyvern", credential_id="cred_123")  # AI login
await page.click(prompt="Add first item to cart")  # AI-augmented click
await page.agent.run_task("Complete checkout with: John Snow, 12345")  # AI task
TypeScript SDK:
import { Skyvern } from "@skyvern/client";

const skyvern = new Skyvern({ apiKey: "your-api-key" });
const browser = await skyvern.launchCloudBrowser();
const page = await browser.getWorkingPage();

// Mix Playwright with AI-powered actions
await page.goto("https://example.com");
await page.click("#login-button");  // Traditional Playwright
await page.agent.login("skyvern", { credentialId: "cred_123" });  // AI login
await page.click({ prompt: "Add first item to cart" });  // AI-augmented click
await page.agent.runTask("Complete checkout with: John Snow, 12345");  // AI task

await browser.close();
Simple task execution:
from skyvern import Skyvern

skyvern = Skyvern()
task = await skyvern.run_task(prompt="Find the top post on hackernews today")
print(task)
Advanced Usage
Control your own browser (Chrome)
Let Skyvern control your existing Chrome browser — with all your cookies, logins, and extensions.
Step 1: Enable remote debugging in Chrome
Open Chrome and navigate to chrome://inspect/#remote-debugging
Click Enable to start the debugging server
You should see: Server running at: 127.0.0.1:9222
[!TIP]
The skyvern init browser command can do this automatically — it opens chrome://inspect/#remote-debugging, waits for you to enable it, and saves the config.
Step 2: Connect Skyvern
Option A — Python Code:
from skyvern import Skyvern

skyvern = Skyvern(
    base_url="http://localhost:8000",
    api_key="YOUR_API_KEY",
    browser_address="http://127.0.0.1:9222",
)
task = await skyvern.run_task(
    prompt="Find the top post on hackernews today",
)
Restart Skyvern service skyvern run all and run the task through UI or code
Connect Skyvern Cloud to your local browser
Let Skyvern Cloud control a Chrome browser running on your machine — with all your existing cookies, logins, and extensions. Useful for automating sites where you're already logged in or behind a VPN.
## One command to start Chrome + create a tunnel to Skyvern Cloud
skyvern browser serve --tunnel
Then use the tunnel URL in your task:
from skyvern import Skyvern

skyvern = Skyvern(api_key="your-api-key")
task = await skyvern.run_task(
    prompt="Download the latest invoice from my account",
    browser_address="https://abc123.ngrok-free.dev",
)
[!WARNING]
Always use --api-key when exposing your browser via a tunnel. Without it, anyone with the URL has full control of your browser. See the security docs.
See the full documentation for all options, manual tunnel setup, and troubleshooting.
Get consistent output schema from your run
You can do this by adding the data_extraction_schema parameter:
from skyvern import Skyvern

skyvern = Skyvern()
task = await skyvern.run_task(
    prompt="Find the top post on hackernews today",
    data_extraction_schema={
        "type": "object",
        "properties": {
            "title": {
                "type": "string",
                "description": "The title of the top post"
            },
            "url": {
                "type": "string",
                "description": "The URL of the top post"
            },
            "points": {
                "type": "integer",
                "description": "Number of points the post has received"
            }
        }
    }
)
Helpful commands to debug issues
## Launch the Skyvern Server Separately*
skyvern run server

## Launch the Skyvern UI
skyvern run ui

## Check status of the Skyvern service
skyvern status

## Stop the Skyvern service
skyvern stop all

## Stop the Skyvern UI
skyvern stop ui

## Stop the Skyvern Server Separately
skyvern stop server
Performance & Evaluation
Skyvern has SOTA performance on the WebBench benchmark with a 64.4% accuracy. The technical report + evaluation can be found here
Performance on WRITE tasks (eg filling out forms, logging in, downloading files, etc)
Skyvern is the best performing agent on WRITE tasks (eg filling out forms, logging in, downloading files, etc), which is primarily used for RPA (Robotic Process Automation) adjacent tasks.
Skyvern Features
Skyvern Tasks
Tasks are the fundamental building block inside Skyvern. Each task is a single request to Skyvern, instructing it to navigate through a website and accomplish a specific goal.
Tasks require you to specify a url, prompt, and can optionally include a data schema (if you want the output to conform to a specific schema) and error codes (if you want Skyvern to stop running in specific situations).
Skyvern Workflows
Workflows are a way to chain multiple tasks together to form a cohesive unit of work.
For example, if you wanted to download all invoices newer than January 1st, you could create a workflow that first navigated to the invoices page, then filtered down to only show invoices newer than January 1st, extracted a list of all eligible invoices, and iterated through each invoice to download it.
Another example is if you wanted to automate purchasing products from an e-commerce store, you could create a workflow that first navigated to the desired product, then added it to a cart. Second, it would navigate to the cart and validate the cart state. Finally, it would go through the checkout process to purchase the items.
Supported workflow features include:
Browser Task
Browser Action
Data Extraction
Validation
For Loops
File parsing
Sending emails
Text Prompts
HTTP Request Block
Custom Code Block
Uploading files to block storage
(Coming soon) Conditionals
Livestreaming
Skyvern allows you to livestream the viewport of the browser to your local machine so that you can see exactly what Skyvern is doing on the web. This is useful for debugging and understanding how Skyvern is interacting with a website, and intervening when necessary
Form Filling
Skyvern is natively capable of filling out form inputs on websites. Passing in information via the navigation_goal will allow Skyvern to comprehend the information and fill out the form accordingly.
Data Extraction
Skyvern is also capable of extracting data from a website.
You can also specify a data_extraction_schema directly within the main prompt to tell Skyvern exactly what data you'd like to extract from the website, in jsonc format. Skyvern's output will be structured in accordance to the supplied schema.
File Downloading
Skyvern is also capable of downloading files from a website. All downloaded files are automatically uploaded to block storage (if configured), and you can access them via the UI.
Authentication
Skyvern supports a number of different authentication methods to make it easier to automate tasks behind a login. If you'd like to try it out, please reach out to us via email or discord.
🔐 2FA Support (TOTP)
Skyvern supports a number of different 2FA methods to allow you to automate workflows that require 2FA.
We love to see how Skyvern is being used in the wild. Here are some examples of how Skyvern is being used to automate workflows in the real world. Please open PRs to add your own examples!
Run this to create your virtual environment (.venv)
uv sync --group dev
Perform initial server configuration
uv run skyvern quickstart
Navigate to http://localhost:8080 in your browser to start using the UI The Skyvern CLI supports Windows, WSL, macOS, and Linux environments.
Documentation
More extensive documentation can be found on our 📕 docs page. Please let us know if something is unclear or missing by opening an issue or reaching out to us via email or discord.
Supported LLMs
Provider
Supported Models
OpenAI
GPT-5.5, GPT-5.4, GPT-5, GPT-4.1, o3, o4-mini
Anthropic
Claude 4.7 Opus, Claude 4.6 (Sonnet, Opus), Claude 4.5 (Haiku, Sonnet, Opus)
Azure OpenAI
Any GPT models deployed to your Azure subscription
AWS Bedrock
Claude 4.7, Claude 4.6 (Sonnet, Opus), Claude 4.5 (Sonnet, Opus)
If you want to chat with the skyvern repository to get a high level overview of how it is structured, how to build off it, and how to resolve usage questions, check out Code Sage.
Telemetry
By Default, Skyvern collects basic usage statistics to help us understand how Skyvern is being used. If you would like to opt-out of telemetry, please set the SKYVERN_TELEMETRY environment variable to false.
License
Skyvern's open source repository is supported via a managed cloud. All of the core logic powering Skyvern is available in this open source repository licensed under the AGPL-3.0 License, with the exception of anti-bot measures available in our managed cloud offering.
If you have any questions or concerns around licensing, please contact us and we would be happy to help.